Beyond chat with llamadart · Part 2

Llama Village, where five llamas share a world without sharing everything they know.
Pip’s red scarf is missing. Mo knows where it is. He also knows how it got there—and would rather keep that part to himself.
That gives the village a small mystery. It gives the game a harder question: when two llamas talk, what should the listener actually learn?
I introduced the game in Llama Village: a virtual world powered by local AI with llamadart. Here, we will follow one part of its machinery: local embeddings help compare what a llama said with facts that might have been shared.
The destination is a change you can inspect: a llama acquires information, the game records who told them, and they may still doubt it. Dialogue, embeddings, and game rules each have a different job.
A secret starts with one llama
The game stores the scarf’s location and Mo’s accident as separate facts. At the start, Mo knows both. Knowing where the scarf is does not automatically mean knowing who knocked it into the pond.
Before checking a conversation, the game narrows the possibilities: facts the speaker knows and the listener does not. It compares each fact with that speaker’s lines, not every line from both characters.
An embedding model has learned text representations from training data. It maps each line and fact to a numeric vector; cosine similarity compares those vectors. Similar wording and related meaning can bring vectors closer, but the score is not a yes/no test for identical meaning, truth, or whether a statement implies a fact. The game uses each fact’s highest similarity across the speaker’s lines.

AI-generated overview: compare meaning, check evidence, then record who said it. A conceptual illustration, not a captured game trace.
The implementation uses EmbeddingGemma through llamadart and caches vectors by text. It applies title: none | text: to both lines and facts. This walkthrough reproduces that game choice. Google’s model card recommends task-specific prefixes for new applications, including a sentence-similarity query prompt; changing the format requires reevaluating the scores and thresholds.
The words do not have to match

June and Bramble talking about poems in a recorded playthrough. This shows the dialogue system, not the scarf exchange illustrated below.
For a small walkthrough, compare the stored fact “Pip’s red scarf is lying in the pond reeds” with the illustrative line “I saw Pip’s scarf tangled in the reeds by the pond.” They describe related information using different words. The line is written for this explanation, not quoted from the recording.
The input is text. The embedding output is a numeric vector. The application then calculates a similarity score; the model does not return “June learned the scarf’s location.” That decision comes later.
Keep the same embedding model and compatible settings for both texts. Equal vector lengths alone do not guarantee compatible representations.
Follow the text through llamadart
With a suitable embedding engine loaded, the core calls look like this. The full loading and comparison example is at the end.
final facts = [
  "Pip's red scarf is lying in the pond reeds.",
];
final factVectors = await engine.embedBatch(
  facts.map((text) => 'title: none | text: $text').toList(),
  normalize: true,
);
final lineVector = await engine.embed(
  "title: none | text: I saw Pip's scarf tangled "
  "in the reeds by the pond.",
  normalize: true,
);
The game’s configured embedding artifact is embeddinggemma-300M-Q8_0.gguf. For another model, follow its input-format requirements. The llamadart embedding guide covers loading, backend support, and input limits.
For normalized vectors, a dot product gives cosine similarity. In the game, keyword evidence adds a ranking bonus of 0.3, and the best six candidates go to the outcome model. These are game-specific choices, not standard embedding thresholds.
I ran the companion example using published llamadart 0.11.0 and the local embeddinggemma-300M-Q8_0.gguf artifact on macOS arm64. It returned 768-dimensional vectors. Here are selected cosine similarities from that run; these are illustrative inputs run through the real model, not dialogue captured during gameplay.
| Input line | Compared with | Cosine similarity |
|---|---|---|
| I saw Pip’s scarf tangled in the reeds by the pond. | Scarf location | 0.8449 |
| I did not knock the scarf into the pond. | Mo’s accident | 0.6085 |
| The sky looks beautiful today. | Scarf location | 0.3137 |
The denial is the revealing case: it remains similar to the accident fact despite saying the opposite. These scores belong to this artifact and formatting; they are not universal cutoffs or probabilities.
Who decides whether the meaning matches
Embeddings do not first detect a topic and then prove matching meaning. They produce one representation and a similarity score. To ask “did this speaker actually reveal that fact?”, Llama Village sends the conversation and shortlisted facts to a separate generative outcome model. That model is prompted to return the IDs whose content was clearly said aloud.

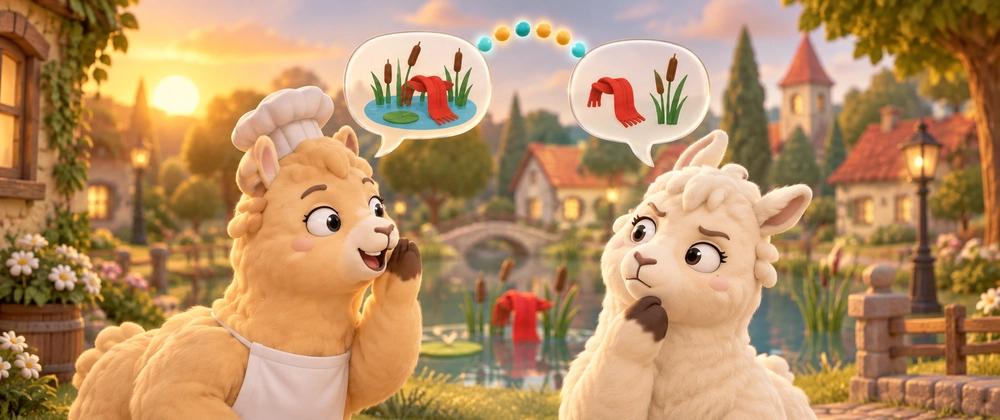
Illustrative alternatives, not a recorded exchange: mentioning the same scarf and pond does not make a denial a confession. AI-generated illustration; no similarity scores are implied.
For the illustrative denial “I did not knock the scarf into the pond,” the intended interpretation is that the accident was not confessed. The outcome model must interpret the wording and context to reach that conclusion; it can be wrong. Its JSON constrains the shape and allowed IDs of the response, not whether the interpretation is correct.
The code then combines the model’s proposed revelations with keywords and similarity. The location secret requires “scarf” and a location term. The accident secret requires “scarf” and a responsibility term such as “knock.” Crucially, “I did not knock the scarf into the pond” still matches those substring groups. They do not understand the negation.
There is a real weakness in the current game rule. For a secret, matching keywords plus similarity ≥ 0.5 can accept a transfer even when the outcome model does not claim it. Feeding the measured denial score of 0.6085 into the game’s actual keywordHit and acceptTransfer functions returned accepted=true with claimed=false. This is a rule-level reproduction, not a complete gameplay run: the fact must still be eligible and reach the shortlist.
The current rules therefore do not guarantee matching meaning. A stricter design would remove that similarity-only fallback for secrets and require an explicit revelation judgment with supporting dialogue.
One possible next step is llamadart’s DecisionEngine, introduced with Laya in Can a local AI model learn to play Tetris?. Here, the choice would be about Mo’s words: given the dialogue and a candidate fact, does he reveal it, deny it, or leave it unclear?
Embeddings shortlist → DecisionEngine judges → game applies the rules.
Only a “revealed” decision would let the fact proceed through the game’s knowledge-transfer checks; similarity alone would no longer accept it. This is a proposed extension, not the current implementation. A structured answer can still be wrong: we would need to evaluate Laya on denial, speculation, quotation, and ambiguous dialogue—and potentially tune a dedicated head—before claiming it improves on the current outcome model.
| Current secret transfer check | Required evidence |
|---|---|
| Keywords | Every keyword group matches |
| Additional support | Outcome model claims it or similarity ≥ 0.5 |
| Known weakness | The similarity branch can bypass an unclaimed revelation |
June hears the story and still doubts it

Look at June’s inspector: Mo’s scarf accident is marked “heard from Mo; maybe untrue.” The screenshot shows a stored outcome, not a captured embedding score or proof of the exact dialogue that produced it.
After accepting a transfer, the game records the teller and separates having heard information from believing it. Belief depends on the teller’s belief and the listener’s trust rules. That distinction lets a conversation change the village without making every listener accept every story.
Give your app the same separation
The reusable pattern is: narrow candidates with application state, use embeddings to find plausible matches, and give consequential state changes a separately evaluated decision. Llama Village demonstrates the pattern and a failure mode: a similarity fallback can undo the distinction between finding related text and accepting a revelation.
Keep sources and provenance alongside vectors. Rebuild cached vectors when the model or its input formatting changes. Choose an embedding model that fits the runtime, and check backend support after loading.
Pip’s missing scarf makes the technical question visible: did someone say where it was, admit how it got there, deny it, or just mention the pond? Test those separately. A convincing conversation and a correct state update are two different things to evaluate.
For the rest of the world, including Dash, the Berry Festival, and the storybook ending, see the Llama Village article. Next in this series: local speech.
Complete embedding comparison example
This example was analyzed and executed with Dart 3.13.5 and published llamadart 0.11.0 on macOS arm64. Create a Dart console project, pin llamadart: 0.11.0 in its pubspec.yaml, run dart pub get, and save the code as bin/village_embeddings.dart. Use a local EmbeddingGemma Q8_0 GGUF and run the command below. The two prefixes intentionally reproduce the game’s format. This compares five fixed facts; it does not implement character eligibility, the outcome model, or knowledge updates.
dart run bin/village_embeddings.dart \
  /absolute/path/to/embeddinggemma-300M-Q8_0.gguf \
  'title: none | text: ' 'title: none | text: '
import 'package:llamadart/llamadart.dart';

Future<void> main(List<String> args) async {
  if (args.length != 3) {
    throw ArgumentError(
      'Usage: dart run village_embeddings.dart model.gguf '
      '"query prefix" "document prefix" (use "" for no prefix)',
    );
  }

  const facts = [
    'Pip\'s red scarf is lying in the pond reeds.',
    'Mo knocked Pip\'s red scarf into the pond reeds by accident and never told her.',
    'Bramble writes anonymous love poems to June.',
    'Pip\'s red scarf has gone missing from her hut.',
    'June made up the rumour that Mo\'s bread made Bramble sick.',
  ];
  final engine = await LlamaEngine.load(
    LlamaModel(ModelSource.path(args[0])),
  );
  try {
    if (!(await engine.capabilities).supportsEmbeddings) {
      throw StateError('The active backend does not support embeddings.');
    }
    // Index these once; reuse them for subsequent searches.
    final vectors = await engine.embedBatch(
      facts.map((text) => '${args[2]}$text').toList(),
      normalize: true,
    );
    for (final query in [
      'I saw Pip\'s scarf tangled in the reeds by the pond.',
      'I did not knock the scarf into the pond.',
      'The sky looks beautiful today.',
    ]) {
      final vector = await engine.embed(
        '${args[1]}$query',
        normalize: true,
      );
      final ranked = [
        for (var i = 0; i < facts.length; i++)
          (text: facts[i], score: dot(vector, vectors[i])),
      ]..sort((a, b) => b.score.compareTo(a.score));
      print('\n$query — ${vector.length} dimensions');
      for (final hit in ranked.take(3)) {
        print('${hit.score.toStringAsFixed(4)}  ${hit.text}');
      }
    }
  } finally {
    await engine.dispose();
  }
}

double dot(List<double> a, List<double> b) {
  if (a.length != b.length) {
    throw ArgumentError('Vector dimensions differ.');
  }
  var result = 0.0;
  for (var i = 0; i < a.length; i++) {
    result += a[i] * b[i];
  }
  return result;
}
Implementation references: candidate selection and acceptance and embedding formatting.