Featured from DEV Community
#devchallenge#kagglechallenge#ai
Congrats to the Kaggle Benchmarking Challenge Winners!
A few weeks ago we teamed up with Kaggle to ask a deceptively simple question: how do you actually...
DEV Community curation
Explore the latest insights, development trends, practical guides, and technology stories from the global developer community.
Featured from DEV Community
A few weeks ago we teamed up with Kaggle to ask a deceptively simple question: how do you actually...
In November 2026, I spent a day building a small tool with Claude Code: a bridge that lets a second...
SGLang-JAX serves the Gemma 4 31B and 26B A4B on TPU and fails to load E2B. A two-file patch adds per-layer embeddings, shared K/V and the double-wide MLP; on one flex-start v5e-1 it then serves 159.9 tokens per second for one request and 4,249.4 at 64, 2.52x vLLM, with GSM8K level with the bf16 JAX engine.
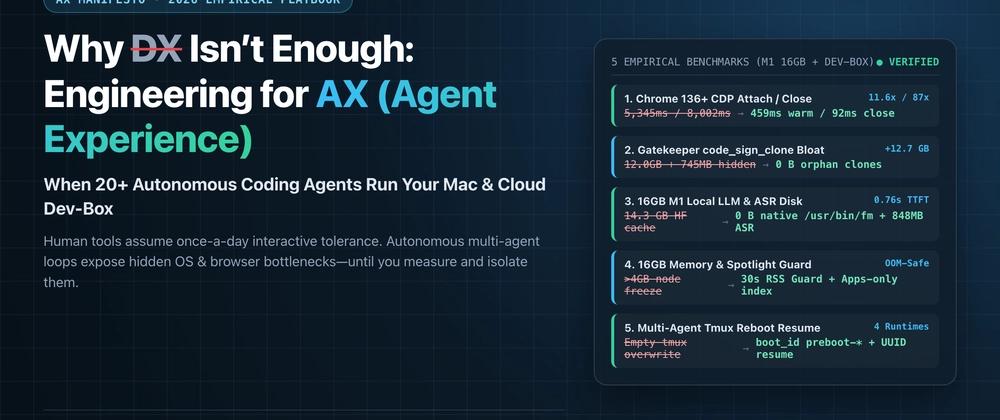
What happens when the hardest-working user on your 16GB Mac and multi-cloud Ubuntu Dev-Box is a fleet of 20+ AI coding agents? Real benchmarks and fixes for 8s Chrome 136+ CDP hangs, 12GB APFS ghost clones, WindowServer freezes, and tmux reboot amnesia.
👋👋👋👋 Looking back on your week -- what was something you're proud of? All wins count -- big or small...
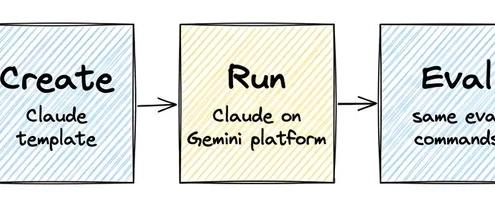
How the Claude extension in Agents CLI takes a Claude Agent SDK agent from install to a validated Cloud Run deploy, with sessions, tracing and eval set up for you.
vLLM, SGLang-JAX, a pure-JAX engine, a Rust model over PJRT, and TorchTPU in Python and Rust serve Gemma 4 E2B on one flex-start v5e-1, with the same prompts, the same 1-to-64-request sweep and the same GSM8K questions. vLLM is the engine that serves out of the box; SGLang-JAX with an E2B patch is the fastest at every load from 8 requests up.
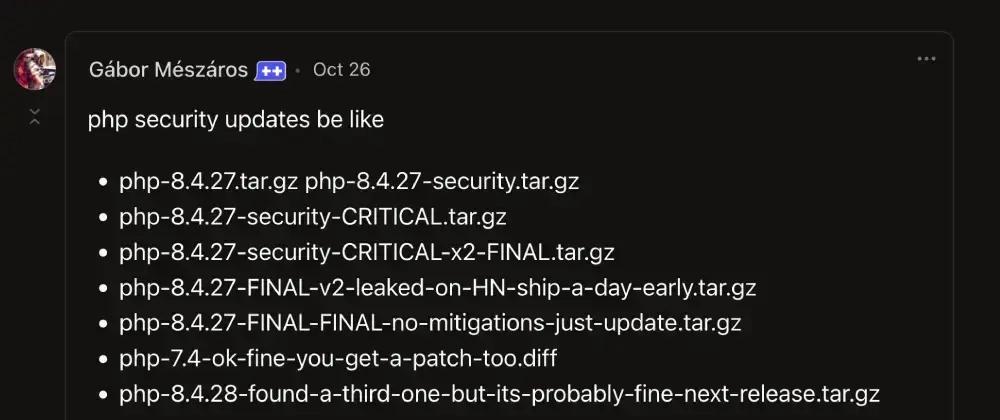
Meme Monday! Today's cover image comes from the last thread. DEV is an inclusive space! Humor in...
LineageOS 24.0 on the Pixel 3a gets mobile data from a Google Fi data-only SIM after four fixes: mobile data on by default, a Fi APN, VoLTE in the carrier settings and a close_range() backport for IPv4. Each one traced from the radio log.
Why Andrew 'Red' Brogdon's insight on client-side functions is critical for Generative UI—and how bloc_signals_genui turns catalog functions into 0ms synchronous reactive signals.
llama.cpp, vLLM, SGLang, mistral.rs, a plain PyTorch engine and LiteRT-LM serve the same 4-bit Gemma 4 E2B on one 8 GB RTX 3050, measured with the same prompts, the same load sweep and the same GSM8K and BFCL questions. GSM8K is level on every engine; vLLM is the fastest up to 16 requests and within 3% of SGLang beyond.
TL;DR: Gemini is the premier frontier model (family) from Google DeepMind. In the current...