Featured from DEV Community
#devchallenge#kagglechallenge#ai
Congrats to the Kaggle Benchmarking Challenge Winners!
A few weeks ago we teamed up with Kaggle to ask a deceptively simple question: how do you actually...
DEV Community curation
Explore the latest insights, development trends, practical guides, and technology stories from the global developer community.
Featured from DEV Community
A few weeks ago we teamed up with Kaggle to ask a deceptively simple question: how do you actually...
👋👋👋👋 Looking back on your week -- what was something you're proud of? All wins count -- big or small...
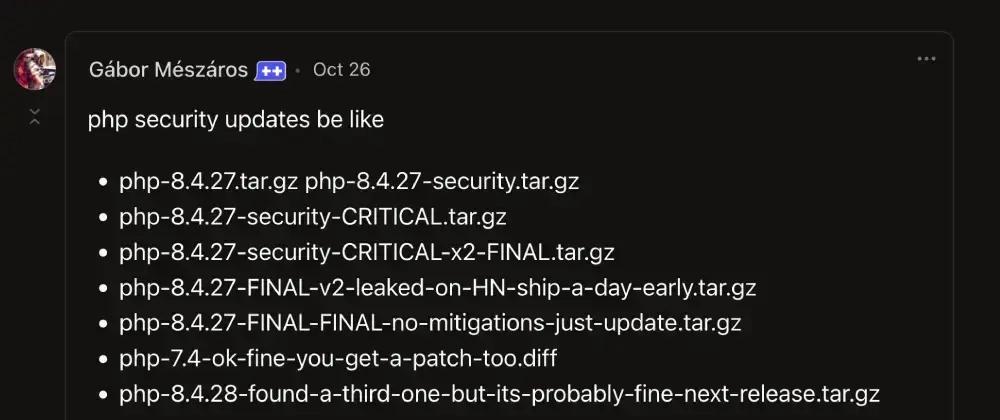
Meme Monday! Today's cover image comes from the last thread. DEV is an inclusive space! Humor in...
LineageOS 24.0 on the Pixel 3a gets mobile data from a Google Fi data-only SIM after four fixes: mobile data on by default, a Fi APN, VoLTE in the carrier settings and a close_range() backport for IPv4. Each one traced from the radio log.
llama.cpp, vLLM, SGLang, mistral.rs, a plain PyTorch engine and LiteRT-LM serve the same 4-bit Gemma 4 E2B on one 8 GB RTX 3050, measured with the same prompts, the same load sweep and the same GSM8K and BFCL questions. GSM8K is level on every engine; vLLM is the fastest up to 16 requests and within 3% of SGLang beyond.
Why Andrew 'Red' Brogdon's insight on client-side functions is critical for Generative UI—and how bloc_signals_genui turns catalog functions into 0ms synchronous reactive signals.
When people call an AI model "open," they don't always mean the same thing. On this week's Prompt...
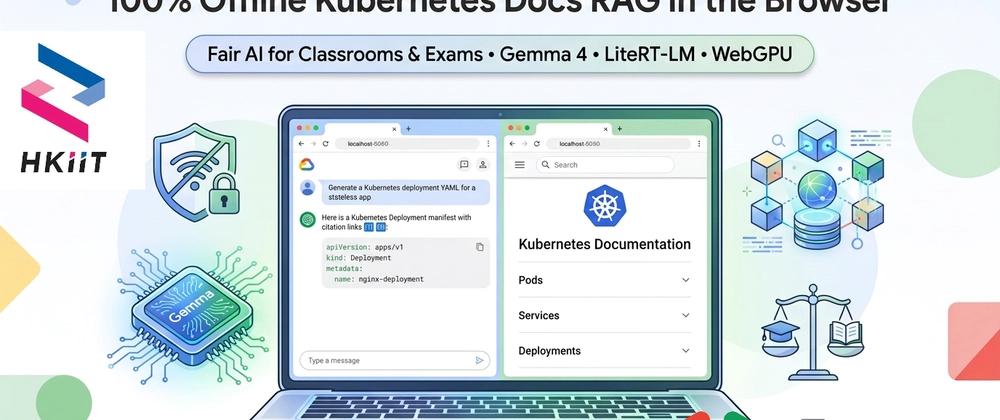
How to enable fair, zero-cost, air-gapped AI assistance in technical classrooms and...
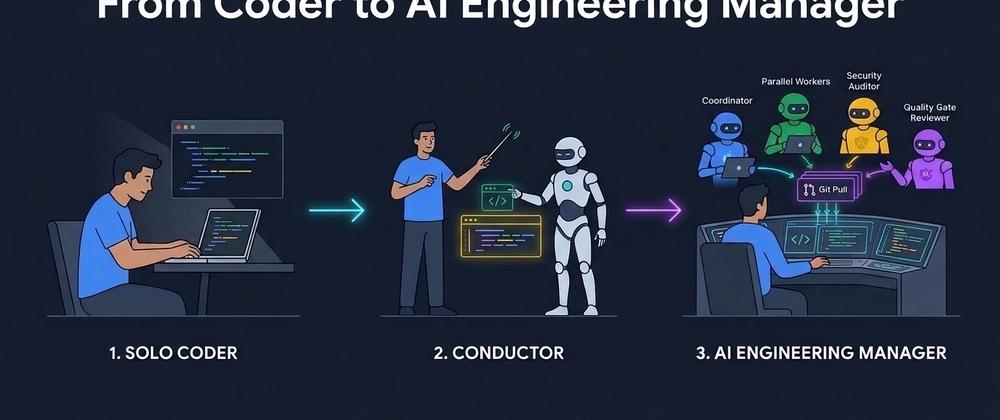
How my workflow evolved from solo prompting in AI Studio to managing a multi-model AI team, running...
Why standard Kubernetes pods fail when AI agents start writing code and how to build a sub-second,...
Want AI to answer in a specific way? Don't just tell it. Show it. In this episode of Prompt Pad,...